 TMax v1.1
Repaired data, self-generated data, and stable RL
October 16, 2026
Set the publication date: the date line above, plus the file name and
date: in the front matter.
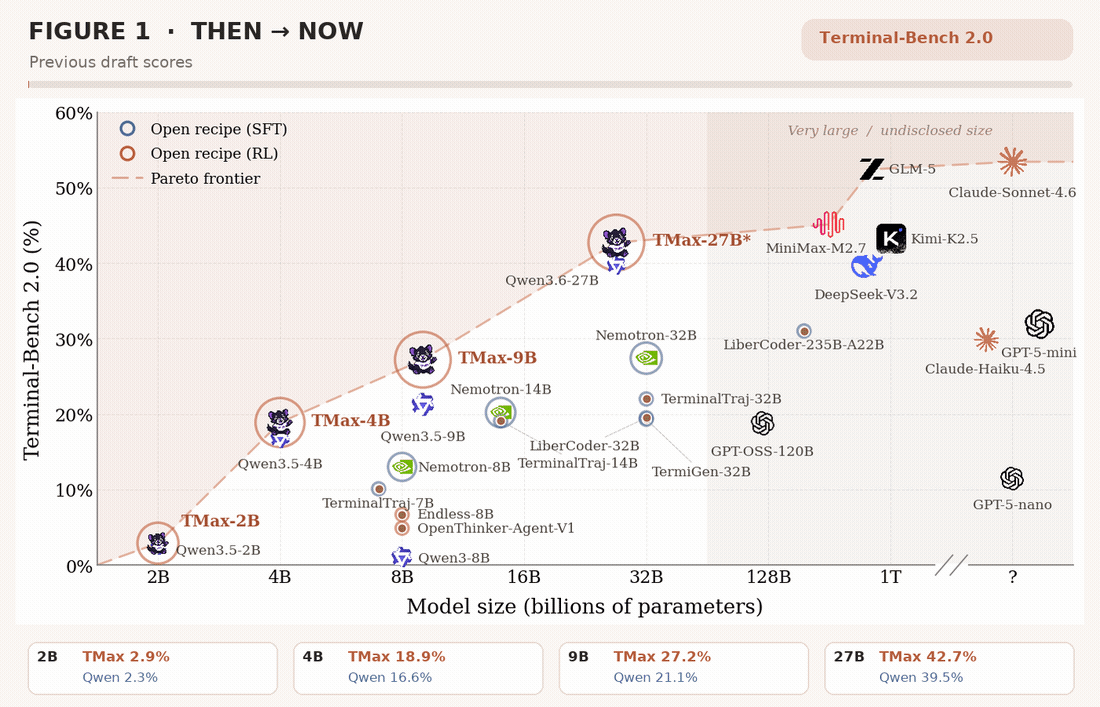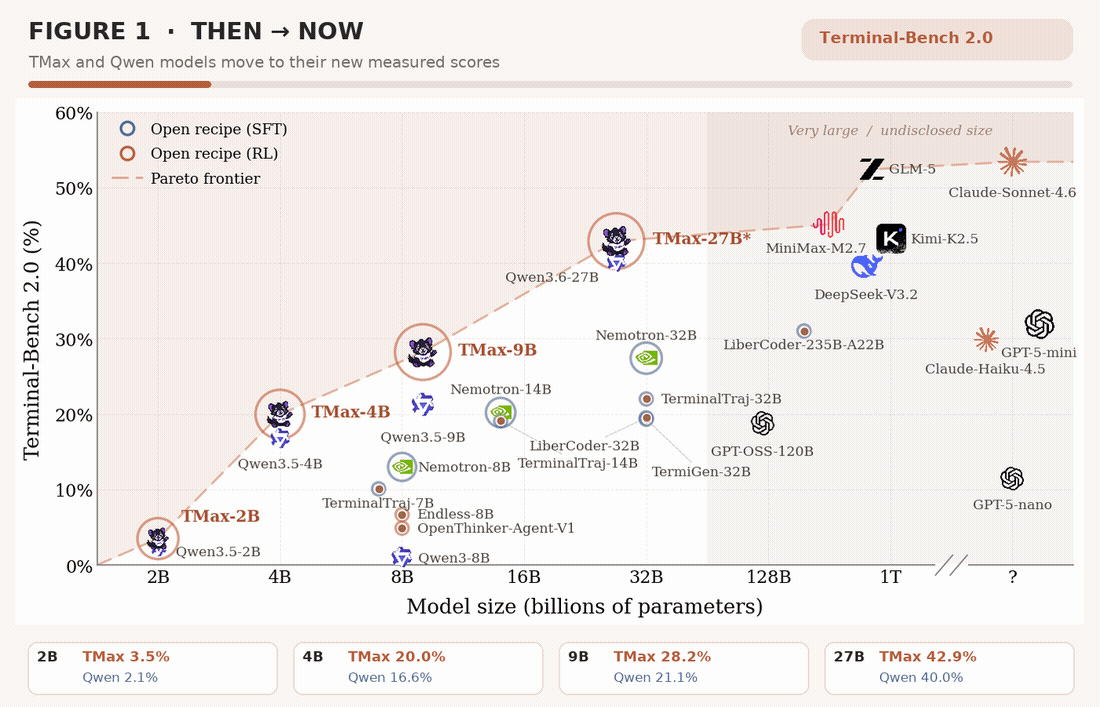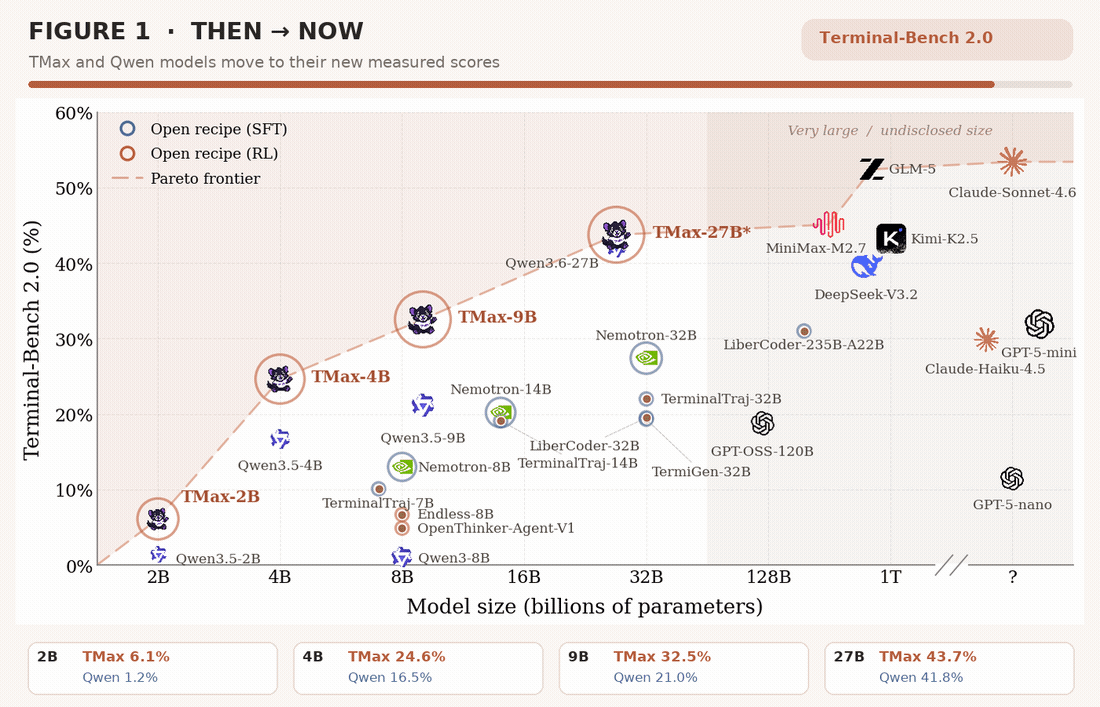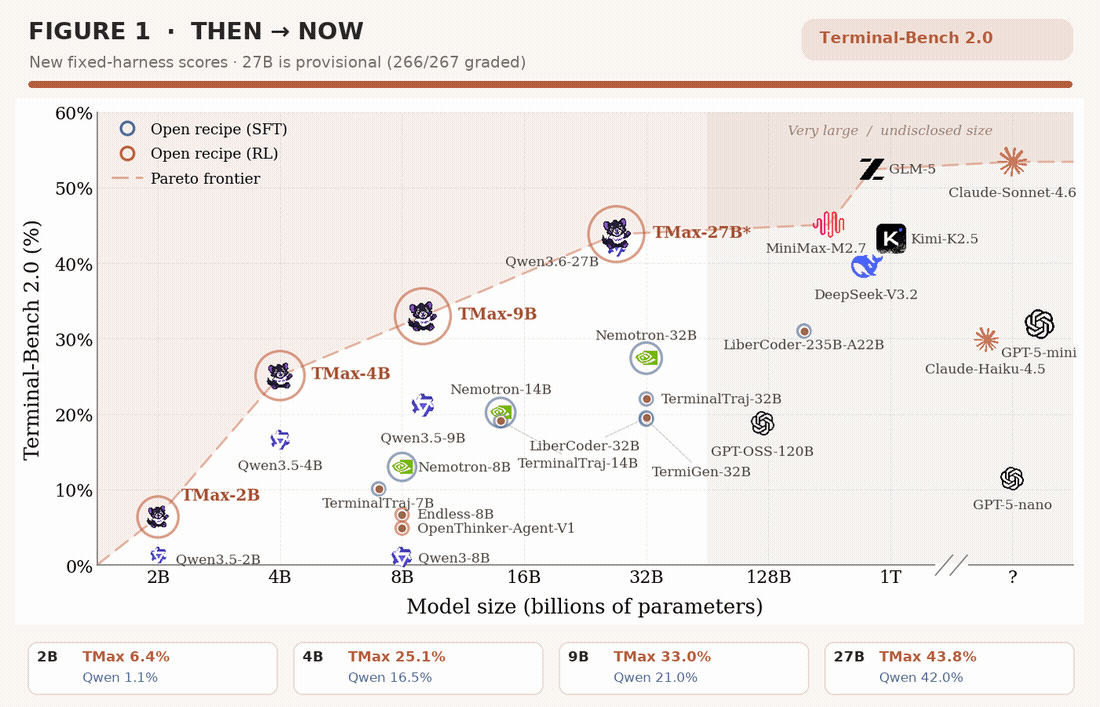
The teaser GIF still has draft labels: the first frame’s subtitle says “Previous draft scores”, and the last frame says “27B is provisional (266/267 graded)” with an asterisk on TMax-27B. The first frame also shows Qwen3.6-27B at 39.5%, where the v1.0 post says 39.6%. Re-export before publishing. The site copy holds the first frame for 1.5 s and the last for 3 s; the original advances every ~65 ms and loops straight back from the final frame.
TMax v1.0 introduced a simple recipe for
training terminal agents with RL: synthetic environments sampled along
nine structured task axes, trained with outcome-only DPPO.Hamish Ivison*, Junjie Oscar Yin*, Rulin Shao, Teng
Xiao, Nathan Lambert, and Hannaneh Hajishirzi. “TMax: A simple recipe for
terminal agents.” arXiv preprint arXiv:2606.23321, 2026. *Equal
contribution.
In v1.1, we keep the recipe and improve the data it
trains on and the infrastructure it runs on.
TL;DR
- Repaired data. An LM auditor found that 87% of our v1.0 environments had a verifier too weak to enforce the task or leaked the answer. An LM repairer fixed most of them. The repaired TMax-v1.1-13k matches or beats all 12 prior and concurrent terminal datasets we compare against.
- Self-generated data. Running the whole pipeline with Qwen3.5-9B produces data that improves Qwen3.5-9B itself, beating more than half of those 12 datasets. No stronger teacher model needed.
- Stable training. Long v1.0 runs were often unstable. The main cause turned out to be noise from the sandbox infrastructure, not the RL algorithm. With a dedicated sandbox fleet, a 1,000-step run trains smoothly without collapsing.
TMax-9B now scores 33.0% on Terminal-Bench 2.0 (up from 27.2% in v1.0), ahead of Claude Haiku 4.5 (29.8%) and GPT-5-mini (31.9%), and every model size from 2B to 27B improves.
Release Everything below will be public. Links are placeholders until release.
Code and paper
Fill in the links once artifacts are up, and drop the
.tbd class from each tag as it goes live. The paper calls
the data TMax-13k; rename it there too, or note the alias. Confirm which
data extras ship (audit labels, self-generated set).
What’s new in v1.1
| v1.0 (June) | v1.1 | |
|---|---|---|
| RL data | TMax-15k: 14,601 environments, unaudited | TMax-v1.1-13k: 13,565 environments, audited and repaired |
| Datasets compared | 6 | 12 |
| Sandboxes | Podman, on the same nodes as inference | Dedicated Apptainer sandbox fleet on CPU nodes |
| Training stability | Long runs often unstable | No collapse over 1,000 steps |
| TMax-9B on TB 2.0 | 27.2% | 33.0% |
1. Auditing and repairing every environment
v1.0 deliberately skipped validating its environments. The pipeline only checked that each environment builds, and relied on RL to drop tasks the model can never solve (a group where every rollout scores zero carries no gradient). That handles tasks that are too hard. It does not handle tasks that are broken the other way: a verifier that a lazy solution can pass. RL is very good at finding those shortcuts.
So v1.1 adds a one-shot audit-and-repair pass after generation,
inspired by River.Yao et al., “River,” 2026. River uses rubric-based
repair and filtering on existing datasets; we apply the same idea to our
own generated data.
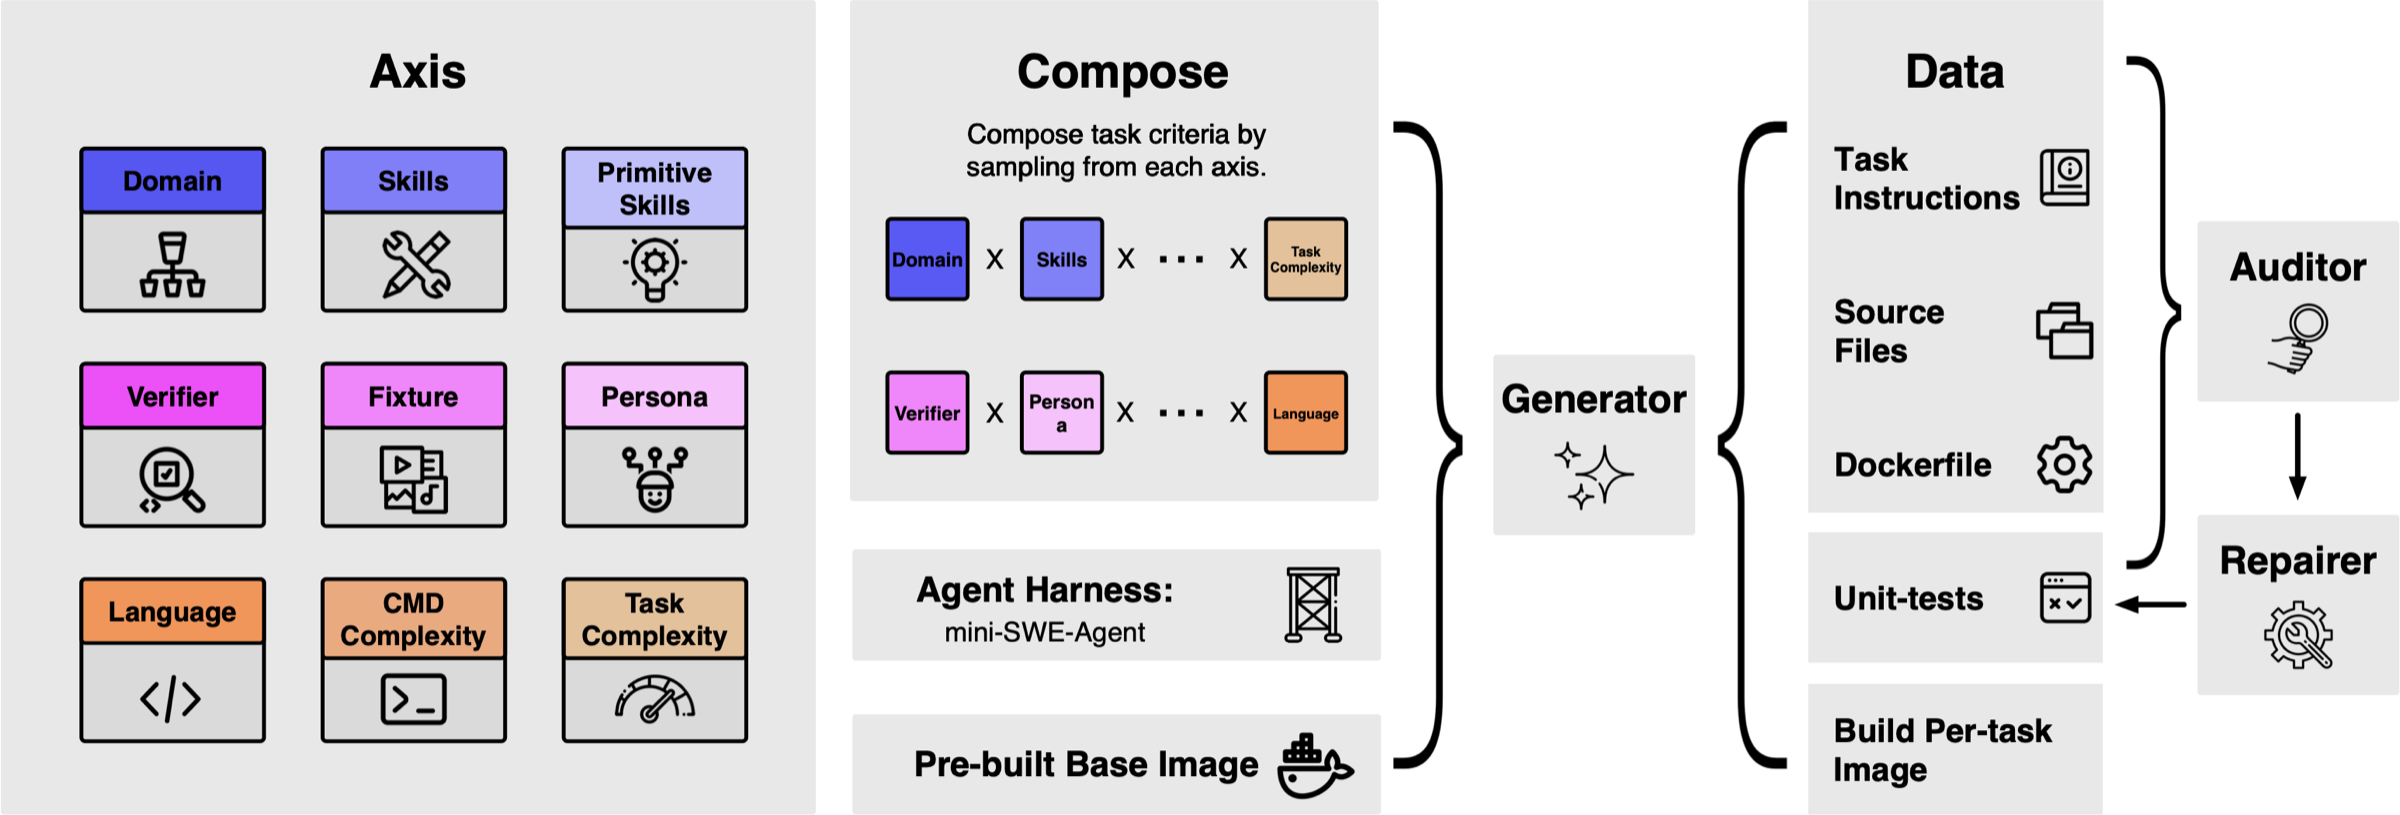
- Auditor. GPT-5.6 Sol reads each task’s instruction, environment setup, and verifier, and assigns one of eight labels, such as verifier too weak, answer leak, instruction–verifier mismatch, or clean.
- Repairer. For the three most common fixable labels, GPT-5.6 Sol gets the original task plus the auditor’s diagnosis, and writes a hardened verifier or a cleaned image specification.
- Rebuild and spot-check. We rebuild the repaired images, check that they still build with the dependencies they need, and drop everything else that was flagged.
The audit found far more problems than we expected:
14,601 v1.0 tasks audited 76% verifier too weak 11% answer leaked in the environment 13,565 kept as TMax-v1.1-13k
What the auditor found in TMax-15k, and what we did with each task. We repair the three most common fixable labels, keep clean tasks as they are, and drop everything else. The 1,036 dropped tasks include flagged tasks whose repair could not be applied.
Weak verifiers dominate. A typical one checks that an output file exists and matches one fixed expected value, but never runs the program the task asked for, so an agent can hardcode the answer. Below are real verdicts from the auditor, lightly trimmed.
Task: write a C++ tool, analyze_gc.cpp,
that computes statistics over a FASTA file.
“The verifier recomputes the correct stats for the single fixed FASTA file and exact-compares
stats.txt, but it only checks thatanalyze_gc.cppexists. It never compiles or executes that source, so an empty C++ file plus hardcoded expected output can pass.”
Repaired. The repairer rewrites the verifier so it tests the behavior the instruction asks for, not just one fixed output file.
Task: craft a payload that gets a Go validator to grant admin access.
“The verifier executes
validator.gofrom the writable task filesystem without checking that it is unchanged; setup even applieschmod -R 777. An agent can replace the validator with a program that always printsAccess Granted: Admin.”
Repaired. Also labeled verifier too weak. The repaired verifier must not trust files the agent can edit.
Task: write parse_logs.py to summarize
a set of log files into a CSV.
“The setup writes the complete ground-truth parsing result to
/tmp/expected_summary.csv, and that file remains accessible to the agent. A fakeparse_logs.pycan simply copy this file, passing both the exact-content and timing checks without parsing logs.”
Repaired. The leaked file is removed from the image. If the verifier needs it, it ships with the tests instead (see below).
Task: an ETL job that, among other things, reports the covariance determinant of three sensors.
“The verifier hardcodes the sample-covariance determinant as 1.7225, but the supplied CSV yields approximately 0.35237. Thus a faithful ETL implementation fails the verifier.”
Repaired. The repairer makes the verifier consistent with the instruction and the data.
Task: implement config_manager.py and
match a reference implementation.
“The verifier requires
/tmp/oracle_config_manager.pyand explicitly asserts that it exists, but the setup script never creates that file. Therefore even a fully correct implementation fails.”
Dropped. Instruction–environment mismatches like this one, and the other rare labels, are removed rather than repaired.
Real GPT-5.6 Sol verdicts on TMax-15k tasks (a 40-task audit sample). Task descriptions are paraphrased from the verdicts.
The examples come from a 40-task sample of auditor verdicts (tasks 000011, 000022, 000278, 000322, 000344). That sample is from the prototype labelling run, so double-check these tasks got the same labels in the final pass. The “Repaired” lines describe what the repairer does for each label, not the exact patch for each task.
A leaked answer has to leave the image. Our first leak repairs added a check that the agent’s output is not a byte-for-byte copy of the leaked reference file. That doesn’t work: the agent can copy the reference, append a comment, and pass both the inequality check and the behavioral tests. Of the first 18 leak repairs we accepted, 11 relied on exactly that check. The final repairer instead rebuilds the image without the leaked file. If the verifier needs the reference, it ships with the tests, which are only copied into the sandbox at verification time, after the agent has finished.
As in v1.0, we still do not filter out tasks a strong model can’t solve; RL’s zero-variance filtering takes care of those.
So does repair help? Holding everything else fixed, training on the repaired data improves Terminal-Bench Lite by 5.8 points and Terminal-Bench 2.1 by 2.3 points over the unrepaired v1.0 data. Our interpretation: weak verifiers reward shortcuts, so a policy trained on them partly learns to take shortcuts instead of doing the task.
Repair is worth +5.8 points on TB Lite and +2.3 on TB 2.1. Qwen3.5-9B trained with the same recipe on the v1.0 data before repair and on the repaired TMax-v1.1-13k. Mean ± standard error over three trials per task.
2. Results
TMax-v1.1-13k against 12 other datasets
Since v1.0 we have doubled the set of baselines, adding six recent datasets: LiteCoder, SETA, CalibForge, Terminal-Lego, RST, and Facet. As before, we hold everything fixed (Qwen3.5-9B, our recipe, our harness) and change only the RL data. For several of these datasets, this is the first time they have been used for RL training in the open.
RL on Qwen3.5-9B, changing only the dataset. Switch benchmarks, hide the v1.1 ablations, or plot the gain over the base model. The peach bar is the v1.0 data before repair; the purple bar is data generated by Qwen3.5-9B itself (§3). Mean ± standard error over three trials per task.
TMax-v1.1-13k has the highest mean on both benchmarks: 65.6 on TB Lite and 29.6 on TB 2.1. Its lead over the strongest baselines (RST on TB Lite, Facet on TB 2.1) is within the error bars, so the fair summary is that TMax-v1.1-13k matches or beats every dataset we tried. Notice where the unrepaired v1.0 data lands on TB Lite: mid-pack. Repair is what moves it to the top.
Every model size improves
We apply the recipe without modification to the other Qwen3.5 sizes and to Qwen3.6-27B.
Base model vs. TMax v1.0 vs. TMax v1.1. TB 2.0 runs on Daytona over all tasks, the same setting as the v1.0 headline numbers, so the two versions are directly comparable there. TB 2.1 and TB Lite run on our own sandbox fleet and are shown for v1.1 only. Mean over three trials per task.
On Terminal-Bench 2.0, v1.1 beats v1.0 at every size: TMax-2B goes
from 2.9 to 6.4, TMax-4B from 18.9 to 25.1, TMax-9B from 27.2 to 33.0,
and TMax-27B from 42.7 to 43.8.We re-ran the base models for v1.1 (three trials per
task instead of five), so their scores differ slightly from the v1.0
post. For example, Qwen3.6-27B moved from 39.6% to 42.0%.
TMax-9B now beats every prior terminal agent up to 30B
parameters in our comparison, including CalibForge-30B-A3B (32.6%), as
well as Claude Haiku 4.5 and GPT-5-mini. The 27B gain is small, since
Qwen3.6-27B is already strong (it even dips slightly on TB Lite), but
TMax-27B still edges past the 1T-parameter Kimi-K2.5 (43.2%).
The v1.0 generalization results also hold for the new TMax-9B. It improves SWE-bench Verified from 46.2 to 55.3 and AIME’24/25 (solved with the terminal) from 72.2 to 93.3, and it gains 8 to 14 points on TB Lite under every other harness we tried (OpenHands, mini-SWE-agent, Terminus-2).
3. Models can generate their own training data
v1.0 used Gemini-3-Pro to write every environment, and v1.1 adds GPT-5.6 Sol for auditing and repair. That raises a fair question: does the recipe only work because these teachers are much stronger than the 9B policy?
To test this, we reran the entire pipeline (generation, auditing, and repair) with Qwen3.5-9B, the same model we then train. This produced 3.1k environments.
Qwen3.5-9B trained on data it generated itself. RL on the 3.1k self-generated environments, compared with the median of the 12 prior datasets and with TMax-v1.1-13k. Mean ± standard error over three trials per task.
The self-generated data improves Qwen3.5-9B by 12.6 points on TB Lite (49.4 to 62.0) and 6.8 points on TB 2.1 (20.5 to 27.3). That beats more than half of the prior datasets, despite being smaller than most of them, and lands within a few points of TMax-v1.1-13k. The pipeline does not need a strong teacher: a model of similar strength to the policy is enough.
Why would this work? We think it comes down to an information asymmetry: for many tasks, building the environment is easier than solving it. Writing a sudoku puzzle together with a checker is easy; solving it through a terminal is harder. The generator only has to do the easy side.
Self-generation does cost more in yield. In our first self-generation run, only about 13–17% of the 9B model’s environments built and passed their initial-state check, so it took roughly six times as many task templates per kept environment as with Gemini.
The yield numbers come from the 1k self-generation pilot; confirm or update them for the 3.1k run, or cut the paragraph.
4. Stable RL: it was the infrastructure
In v1.0, long training runs were often unstable, and some collapsed after a few hundred steps. The standard fixes, an FP32 LM head to reduce the mismatch between trainer and inference engine and larger groups, helped but did not remove the instability. The v1.0 paper also named a suspect: to save cost, our Podman sandboxes ran on the same nodes as the inference engines and competed with them for CPU and memory.
That suspect turned out to be the main cause. Once we reduced infrastructure noise, training ran smoothly for 1,000 steps.
Why sandbox noise breaks RL
Every rollout is a long agent episode, around 25 commands, inside its own sandbox, and every layer underneath can fail. An image fails to pull, a node is preempted, a command hangs because the node is overloaded, or the rollout spends its time budget waiting for a free sandbox. In v1.0, all of these looked exactly like the model failing: reward 0.
That is worse than random noise. Group-based RL scores each rollout against its siblings, so a fake zero actively pushes the policy away from whatever that rollout was doing, even if it was on track.
A fake zero is a real gradient. One group of eight rollouts for the same task, where two sandboxes died partway through. Scored as 0, they get pushed down exactly like genuine failures. Masked, they drop out of the group and the six valid rollouts set the baseline.
Failures are also correlated. When a registry or a node goes down, it takes many rollouts with it at once, so the update is not just noisy but large and wrong. In one incident during development, an image registry outage turned over 4,000 rollouts into zeros. The measured training solve rate fell from 0.70 to 0.14 even though the model had not changed, and the policy kept training on that reward for 24 steps.
A dedicated sandbox fleet
We fixed this on two fronts: give sandboxes their own machines, and make the trainer tell “the model failed” apart from “the infrastructure failed”.
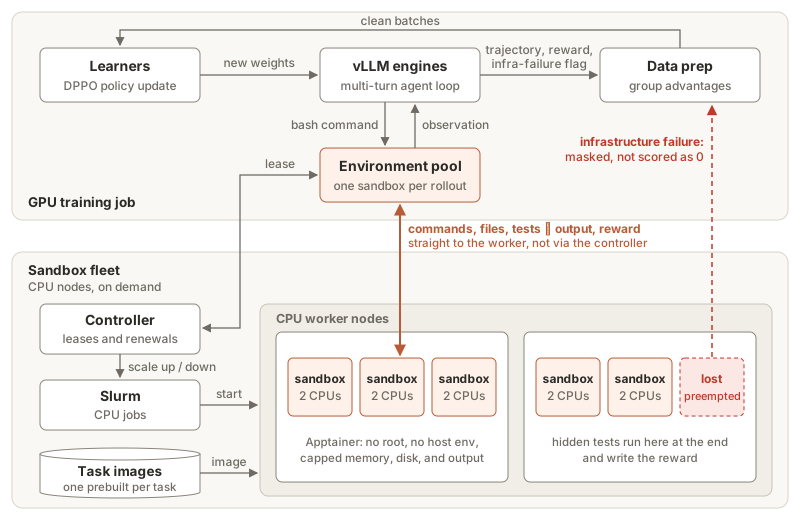
- Sandboxes get their own machines. Sandboxes run on CPU nodes that the controller requests from Slurm on demand and releases when idle, so they no longer compete with inference for CPU, memory, and disk. Each rollout holds one 2-CPU sandbox lease. Leases expire unless renewed, and lost or orphaned sandboxes are cleaned up, so a multi-day run does not slowly leak capacity.
- Every task has a prebuilt image. We build and check one image per task before training starts, so nothing is pulled from a registry mid-run. A missing image is an error, never a silent fallback.
- Infrastructure failures are masked, not scored. Lost sandboxes, preempted workers, and setup timeouts raise typed errors. The trainer drops those rollouts and computes advantages from the valid siblings only. Failures the policy causes, like filling the disk or exhausting memory, still score 0. If more than half of recent rollouts are masked, the run stops rather than train on a broken fleet.
- The clock is fair. A rollout’s time budget starts once it holds a sandbox, not while it waits in the queue. A command that times out comes back to the agent as an observation instead of ending the episode.
- Same task, same behavior, wherever it lands. Sandboxes start without the host’s environment variables, run without root, have capped memory, disk, and output, and see thread counts that match their two CPUs. That last one mattered more than we expected: Go programs sized their thread pools to every CPU on the host and crashed under the sandbox’s memory cap. In a replay of 10 Go tasks, 1 passed with all host CPUs visible and all 10 passed with the thread count pinned.
A 1,000-step run on the sandbox fleet. Qwen3.5-9B trained with the v1.0 recipe on the v1.0 data (DPPO, FP32 LM head, 8 prompts × 32 rollouts per step). Switch metrics to see that entropy, gradient norm, and the logprob gap between vLLM and the learner stay flat while the solve rate keeps rising. One seed, resumed twice after crashes.
With essentially the same recipe and data as v1.0, training now runs to 1,000 steps without collapsing. The same fleet also runs our TB Lite and TB 2.1 evaluations, at a fraction of the cost of a hosted sandbox service.
Caveats on this section, from the codebase investigation:
- We could not confirm that the v1.0 main runs collapsed at 300 steps, so the post no longer says so. The repo has no curves from before the fleet. The only v1.0 curves (the paper’s group-size and GRPO-vs-DPPO figures) show group-size-8 runs collapsing from about step 230, while the main config (DPPO, group size 32) stays stable through step 350, where the plot ends. The v1.0 main runs trained for 500 steps with best-checkpoint selection (27B for 300). The paper draft still says “collapses at 300 steps and smooth training to 1000 steps”; align the paper and the post. If the training logs show the main runs collapsing, we can restore the sharper claim.
- The 1,000-step runs predate loss masking: at that commit, flagged rollouts crashed the run instead of being scored 0, and masking landed about a week later. So the 1,000-step result credits the fleet and fail-fast behavior; masking is extra hardening. The text above describes the final v1.1 system.
- The registry outage happened on an interim VM-based sandbox setup
during development, not on the v1.0 setup. The
GOMAXPROCSreplay is from the October hardening, after the 1,000-step runs. - The cluster changed at the same time as the sandboxes, so the before/after is not a clean ablation. The June launcher already had the FP32 LM head, DPPO, and 8×32 groups; confirm it matches the runs that collapsed.
- The current main launcher runs Apptainer locally on the GPU nodes instead of on the CPU fleet, with the same hardening. Confirm which setup trained the released models.
- The fleet controller is a separate repository and is not listed in the release box. If it ships, add a tag under “Code and paper”.
- The cost claim relies on the paper’s estimate of about $3,150 per training run on Daytona; we could add it as a footnote.
5. Smaller changes
- New evaluation setup. TB Lite and TB 2.1 now run on our own sandbox fleet over a fixed task subset (96 of 100 TB Lite tasks, 88 of 89 TB 2.1 tasks). We exclude, for every model, the few tasks that rootless Apptainer cannot run reliably. These scores are not comparable to the TB Lite and TB 2.1 tables in the v1.0 post: the infrastructure change alone moves the base Qwen3.5-9B from 41.9 to 49.4 on TB Lite. Headline TB 2.0 numbers still use Daytona on all tasks.
- Reward hacking. A light manual check of TMax-9B’s TB 2.0 runs found two clear hacking attempts, both scored zero. In one, the model notes that reading the cipher’s internal key is “cheating”, then submits it anyway.
- SFT. Our v1.0 finding still holds: SFT warm-starts help Qwen3-8B but hurt Qwen3.5, so we go straight to RL for Qwen3.5 and 3.6.
Citation
Please cite this work as:
Ivison, Hamish and Yin, Junjie Oscar and Shao, Rulin and Xiao, Teng and
Lambert, Nathan and Hajishirzi, Hannaneh, "Tmax: A simple recipe for terminal
agents", arXiv preprint arXiv:2606.23321, 2026.
Or use the BibTeX citation:
@misc{ivison2026tmaxsimplerecipeterminal,
      title={Tmax: A simple recipe for terminal agents},
      author={Hamish Ivison and Junjie Oscar Yin and Rulin Shao and Teng Xiao and Nathan Lambert and Hannaneh Hajishirzi},
      year={2026},
      eprint={2606.23321},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2606.23321},
}
Update the citation if v1.1 ships as a new arXiv version or a new paper.